Great to be here on the new forum! Focus on Explainable Data Matching
Hi everyone,
Great to see the community transitioning over to the new platform!
For those I haven't caught up with since the KNIME Data Summit in Munich, I wanted to drop a quick update on our latest focus at exorbyte.
While we’ve been deeply involved in agentic data retrieval and scaling workflows to billions of rows, our core priority right now is Explainability. When grounding AI or handling complex identity resolution, black-box matching just doesn’t cut it for enterprise workflows. You need to know exactly why a match was made.
Through the exorbyte M|BOX extension for KNIME, we are making large-scale data matching completely transparent and deterministic. Check out the snippet below, our nodes don't just find the data; they provide a granular, field-by-field breakdown of the matching logic, qualities, and applied penalties (like alias rules or typo tolerances).
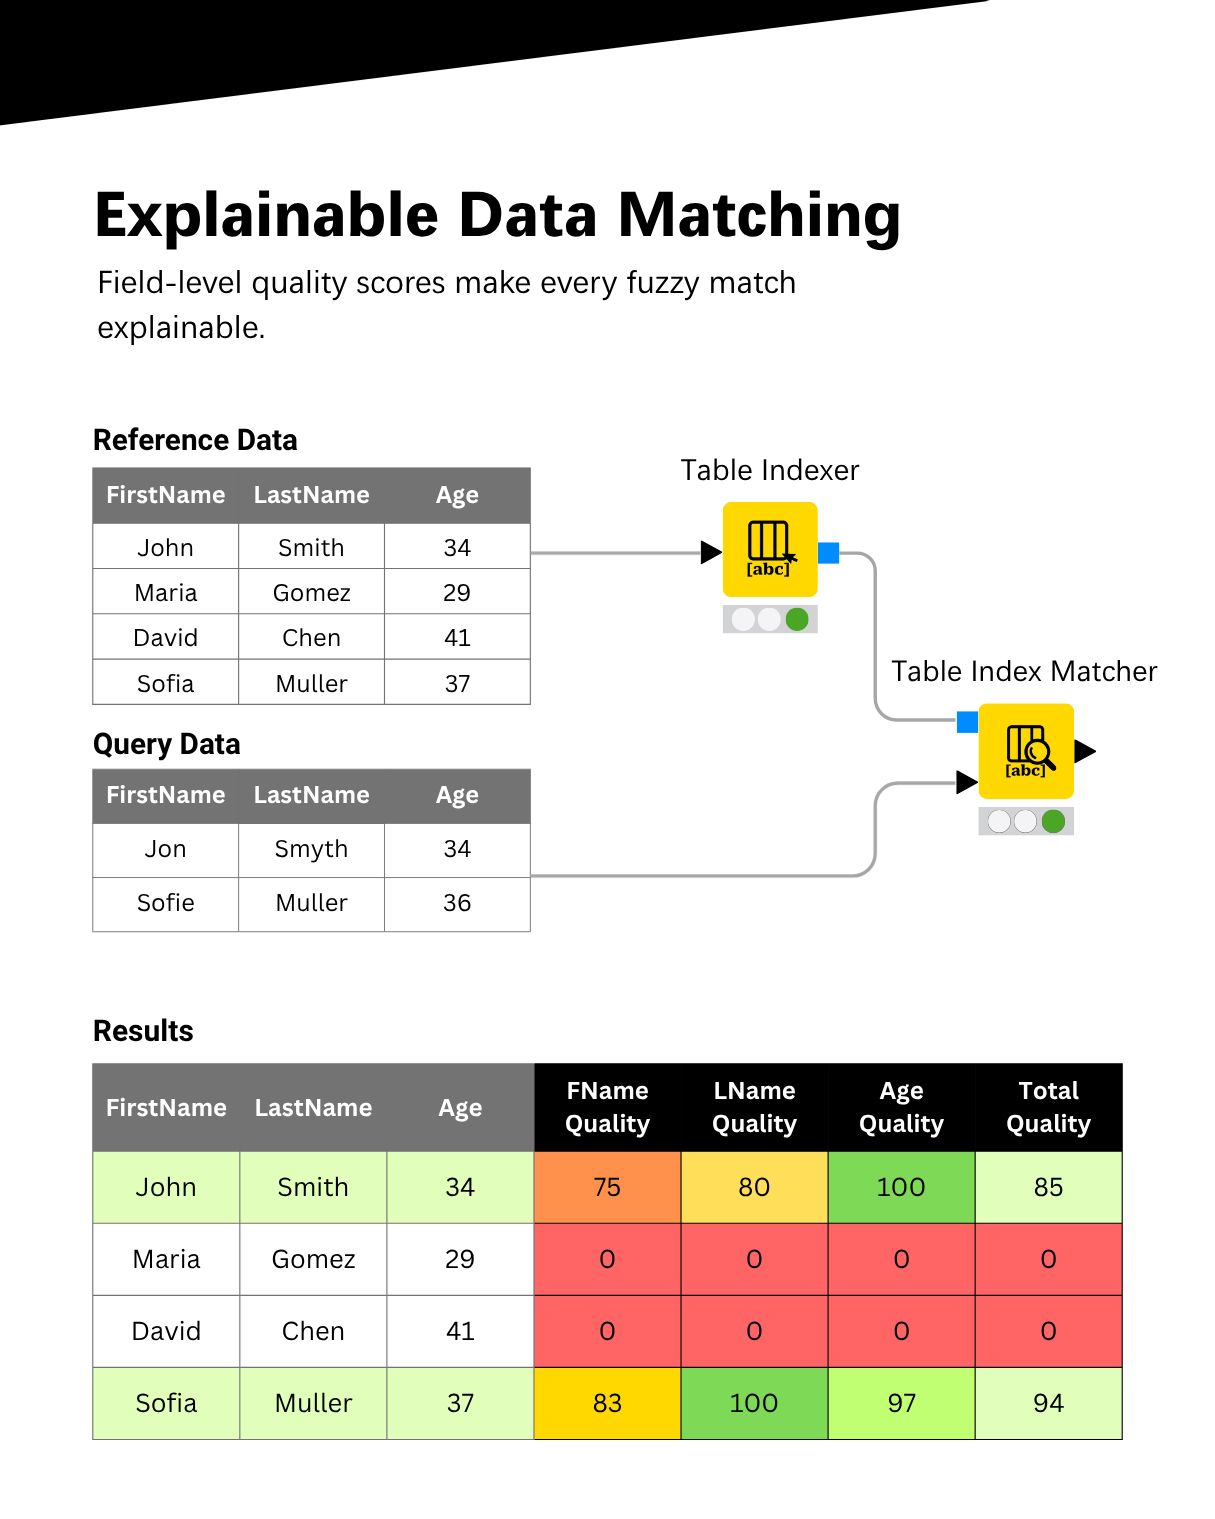
Instead of guessing, your downstream KNIME workflows get a verifiably reliable, auditable data foundation before it ever hits an LLM or database.
Looking forward to diving into the threads here. If you're tackling tricky deduplication or trying to build explainable data matching pipelines, let’s swap ideas!
Best,
Ahmad Varasteh
Product Owner | exorbyte GmbH