Ways to speed this up? 10M + rows
Hi Folks
looking for suggestions as to how i can speed this up
I have a data set with normally 10M+ rows
within this i have a col with anything from 5+ unique values normally not exceeding 100.
For each unique value in that col i need to filter rows then perform a data integrity check
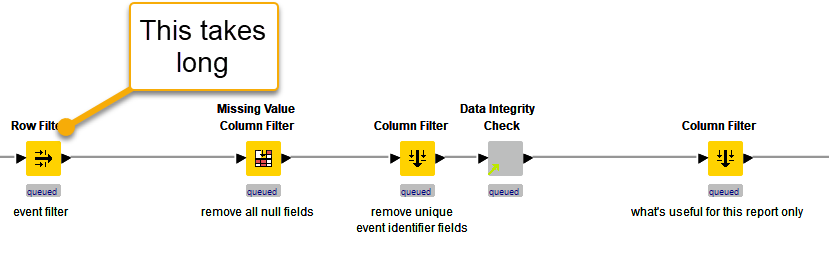
The row filter takes a massive amount of time due to the number of rows, and when i put this in a loop, well, that’s multiplied by no of unique values
Any ideas as to how i can speed this up.
I was thinking of a quick way to split out the data dynamically into the relevant groups, then running parallely but haven’t figured out how yet…
cheers
Gavin