Unstructured text mining from PDF
Dear Knime Members!
I have an example document. I’d like to retrieve the phone call and SMS information from the document and process it later with Spacy.
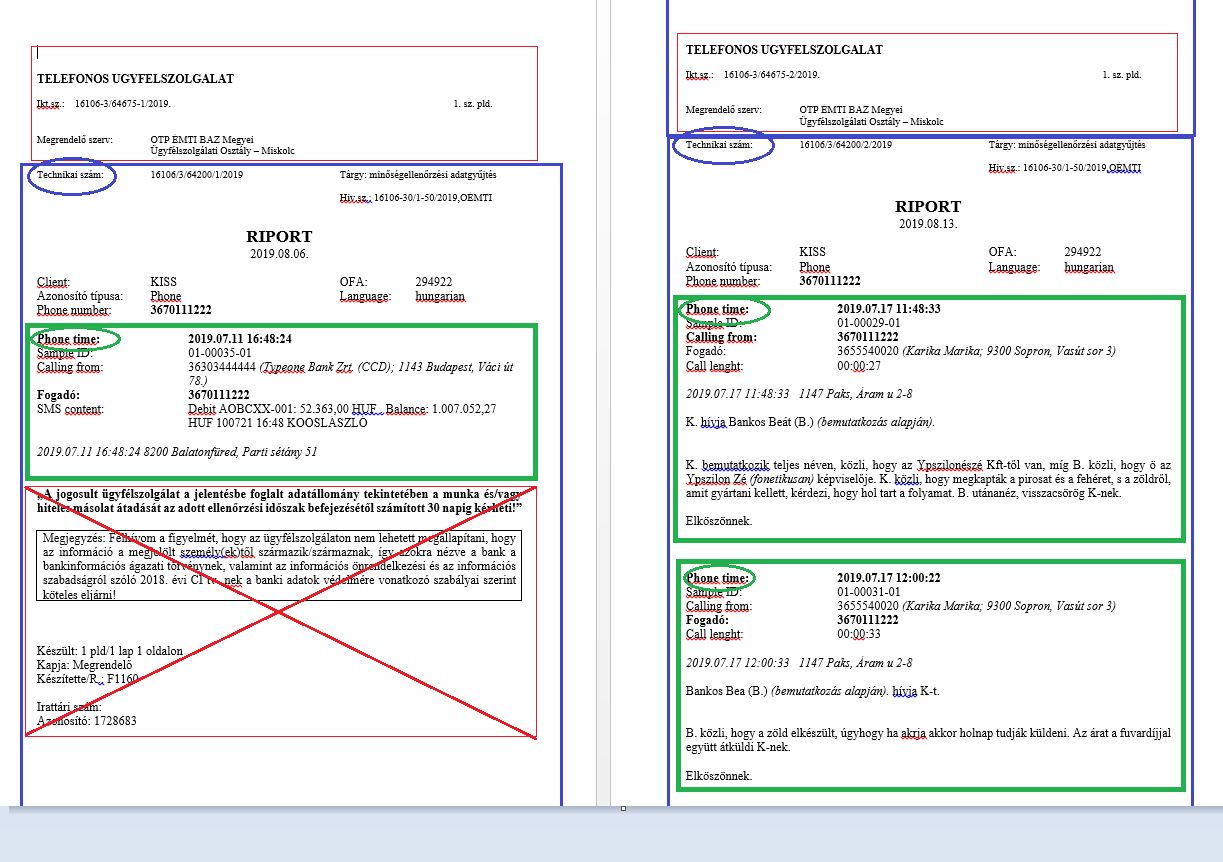
I have split the multipage (up to 100) PDF into several main blocks.
The information at the beginning of the document (header and heading data within red frame) is not relevant until the first Technical Number.
The most important blocks (within blue frame) run from Technical Number (in Hungarian “Technikai szám”) to the next Technical number. The Technical number is marked with blue oval.
Within the main blocks, there are one, or more sub-blocks. These are in green frames. At the beginning of the green frames there is the Phone time.
The bold text and the rest of the sub-block are no longer required, but I can’t find a way to remove the unnecessary part.
Because the text is not structured, I do not know how many lines the block contains and where the extra line is added to the end.
Unfortunately it cannot be specified to delete or trim the last 10 lines. Or I don’t know the first line of the text that’s written from the beginning of the block.
I have attached the process and the sample PDF included in a Word document.