Questions on overfitting and H2O model deplyoment
Greetings everyone!
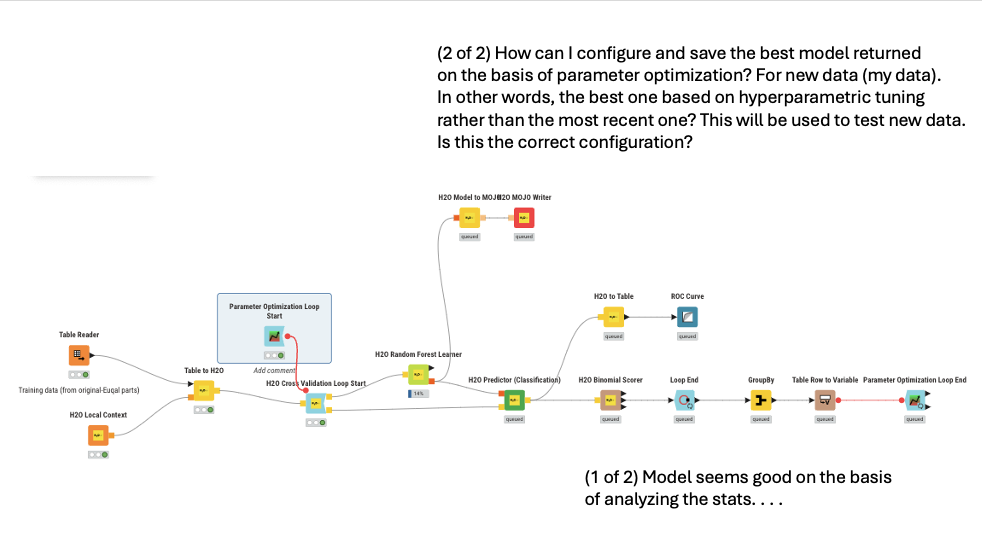
After spending quite a few hours on configuring the H2O workflow below to make predictions on the basis of a train and test data set, I’m starting to think about applying this model to my data --which the model hasn’t seen yet. This will be my first model ever. I think the term is model deployment.
The workflow below shows the current setup with the H2O to MOJO and MOJO writer nodes linked in the top. Three questions:
Is this the right setup?
What do I check to confirm the absence of substantial potential overfitting?
How can I configure the nodes to ensure only the best model is saved rather than simply the most recent?
Any help would be most welcome. Loving this process so far!
Many thanks!
~Cole K.