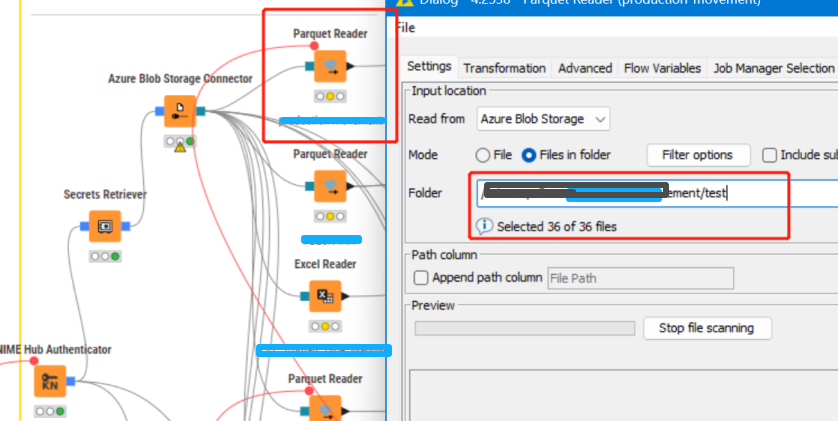
Performance Optimization for Reading Parquet Data from Azure Blob in KNIME
Hi everyone,
We’ve encountered a performance bottleneck when using KNIME to read Parquet data from local Azure Blob Storage, and we’d like to ask if anyone has optimization solutions:
Data Scale: A total of 33 Parquet files, with a total size of less than 100M and about 900,000 rows in total
Current Issue: It takes about 1 hour to read the data in the local environment; even when executed on KNIME Hub, it still takes dozens of minutes
Temporary Workaround: Currently we can only reduce the waiting time by compressing the data volume, but this is not a long-term solution
I wonder if anyone has performance optimization suggestions for Azure Blob + Parquet reading? For example, node configuration adjustments, parallel reading strategies, or other efficient reading methods?
Thanks for your sharing!