PDF TIKA / PARSER - Extract data
HI,
Here is a PDF
20240813DEA01_last_times_fr.pdf
from which I would like to extract only the highlighted information on PAGE 1
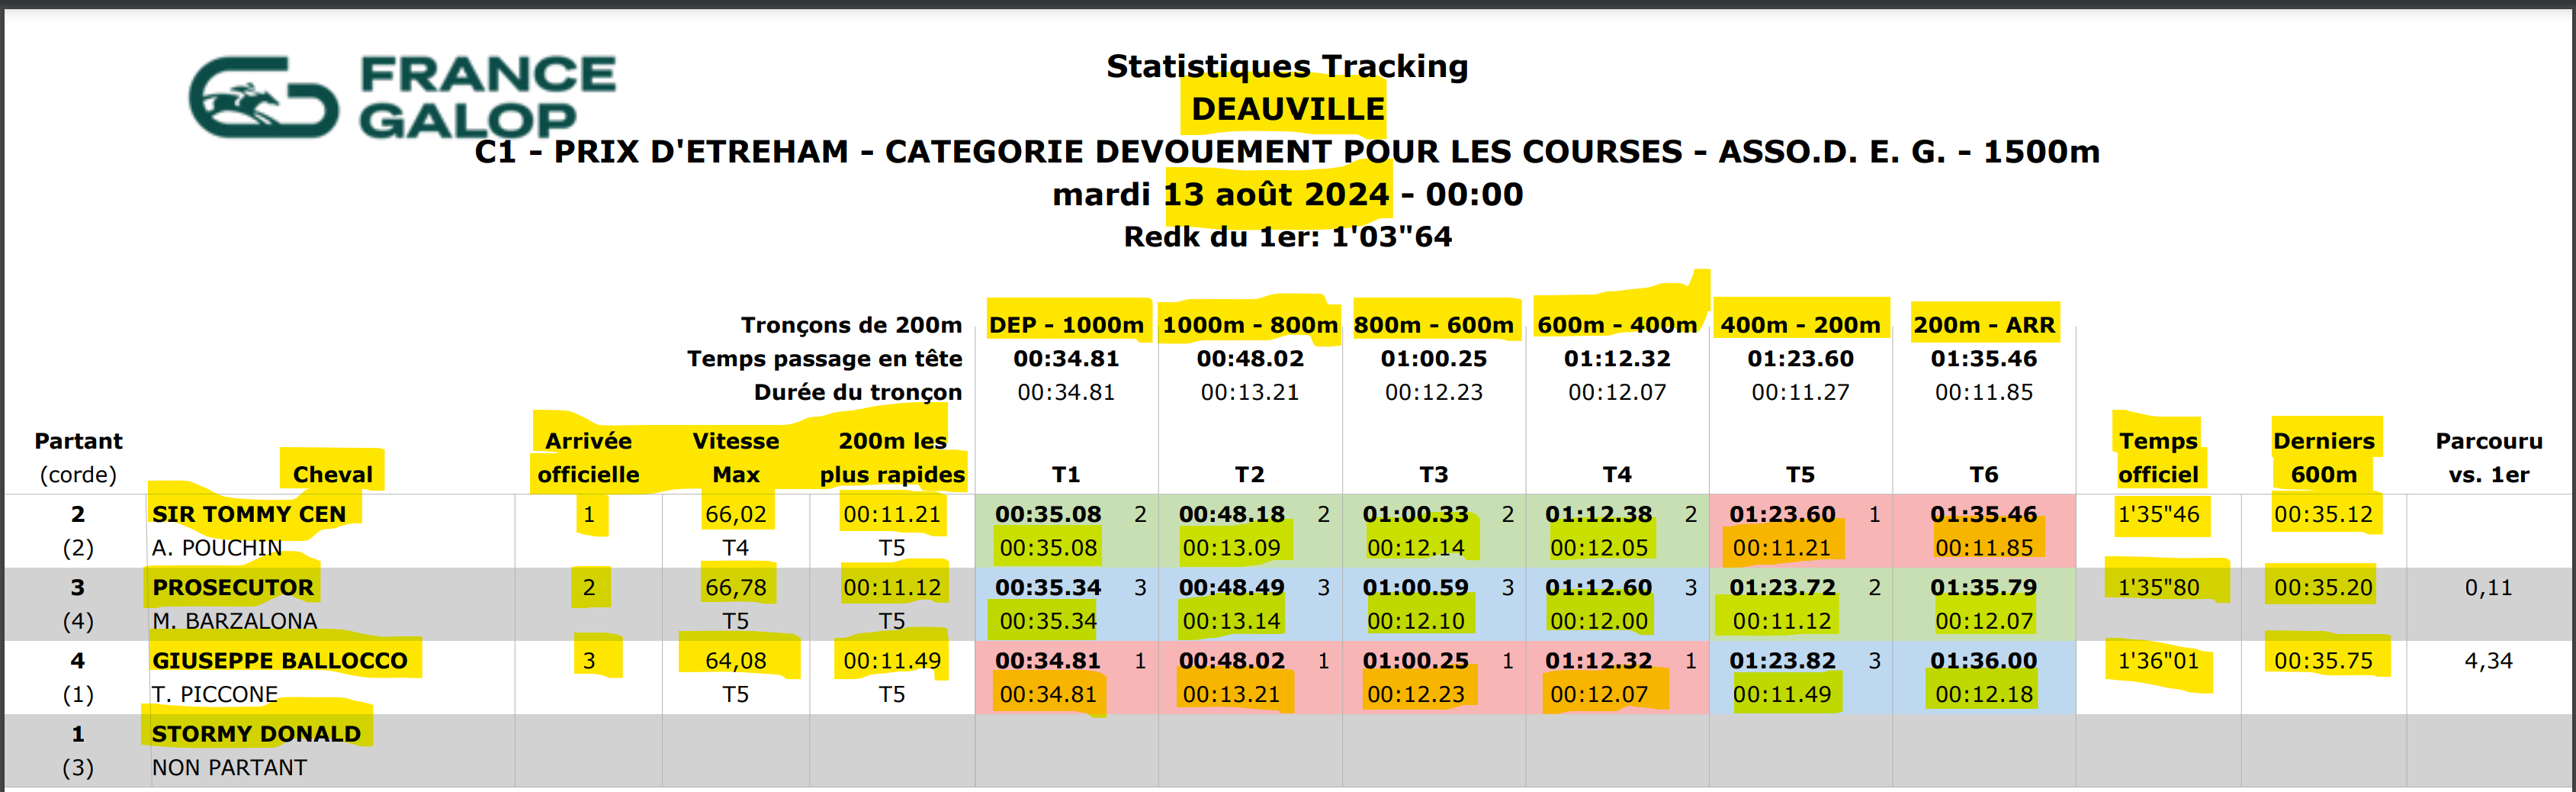
The idea is to end up with a table like this :
My plan is, of course, to use TIKA PARSER or PDF PARSER, but the problem starts afterward. If anyone can help…
Thanks
Br