Output semantics and missing coverage indicators in P-median, MCLP and LSCP nodes
Hi
I am currently experimenting with the Location Analysis nodes (P-median, MCLP and LSCP) and I have some questions regarding the interpretation of the output, specifically for MCLP and LSCP.
P-median
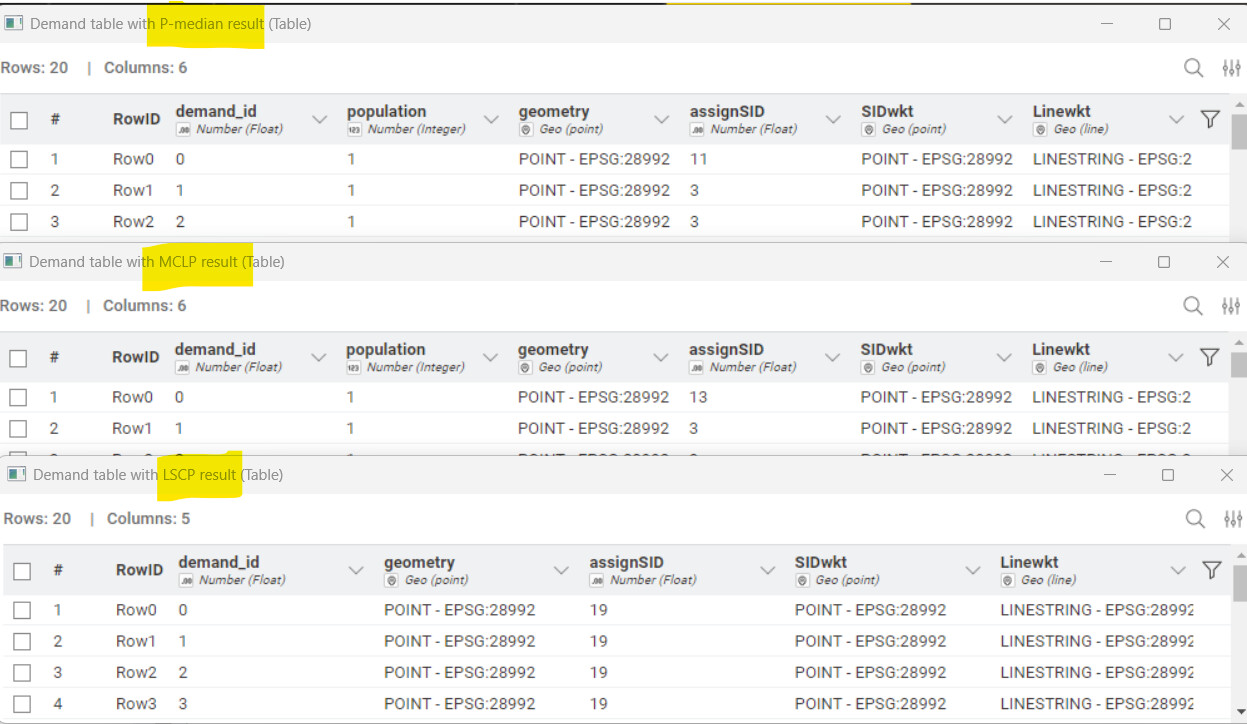
For the P-median node, the output is clear and intuitive:
*
demand points are assigned to selected supply locations
*
distances and assignments reflect the actual optimization result
No issues here.
MCLP (Maximum Covering Location Problem)
For MCLP, demand is considered covered if it lies within a critical spatial cost.
What confused me initially:
*
all demand points are still assigned to a supply, even when they are outside the critical distance
*
the output does not contain an explicit coverage indicator (e.g. 0/1 or boolean)
I now understand that:
*
assignment ≠ coverage
*
uncovered demand is still assigned, but does not contribute to the objective
To make this explicit, I manually reconstructed a
coveredcolumn using a Rule Engine based on distance ≤ critical spatial cost.
Question:
Is the absence of a coverage indicator in the MCLP output expected, or is there a way to retrieve this directly from the node?
LSCP (Location Set Covering Problem)
For LSCP, I observed similar behavior:
*
all demand points are assigned to the same supply_id
*
changing distances or thresholds does not change this assignment
*
again, no explicit coverage or feasibility indicator is present
My understanding is that:
*
LSCP only decides which supply locations are selected
*
assignment is secondary and not optimized
*
coverage is a hard constraint, but not exposed in the output
Questions:
*
Is this behavior intended?
*
Is manual reconstruction of coverage from the distance matrix the recommended approach?
*
Should the assignment column be ignored for LSCP interpretation?
Feature request
Would it be possible to enhance the MCLP and LSCP nodes with clearer output semantics, for example:
*
an explicit
covered(0/1) column for demand points
*
a clear selection flag for supply locations
*
or documentation clarifying which output columns are meaningful per model
This would greatly improve interpretability and reduce trial-and-error when working with these otherwise very powerful nodes.
Gr. Hans