Outliers base on K -means
Hi,
I need to solve a problem and I think I know how to do it but I’m not sure.
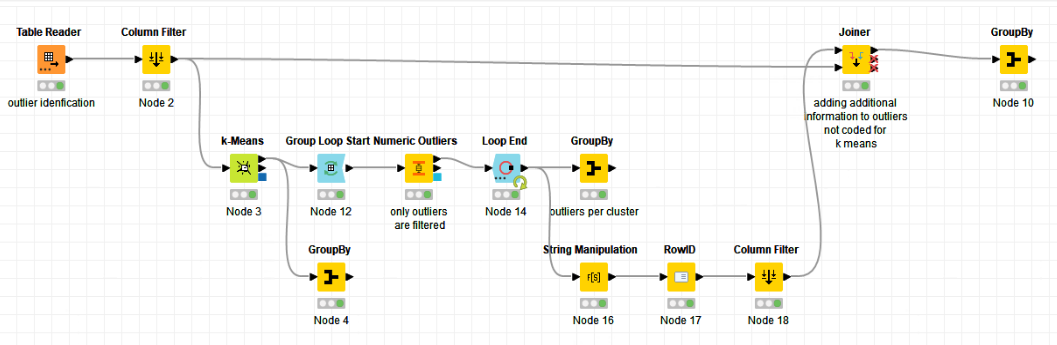
I have a set of data which are partitioned into clusters via K-means.
Then for each cluster I want to find out the Outlier. For this there is a node Numeric Outliers .
I have set the parameters for Outliers.
For each cluster I evaluated the outliers separately.
Because I have selected only a certain set of columns according to the node PCA , so then I will tighten the infomation before the PCA to be able to assess the already data or check it .
Is this the correct approach I am not sure.
I did not find any solved example for my problem .
Marek