Need help to validate this workflow approach
Hi I am performing NLP Text Classification Prediction model in KNIME.
This is my workflow
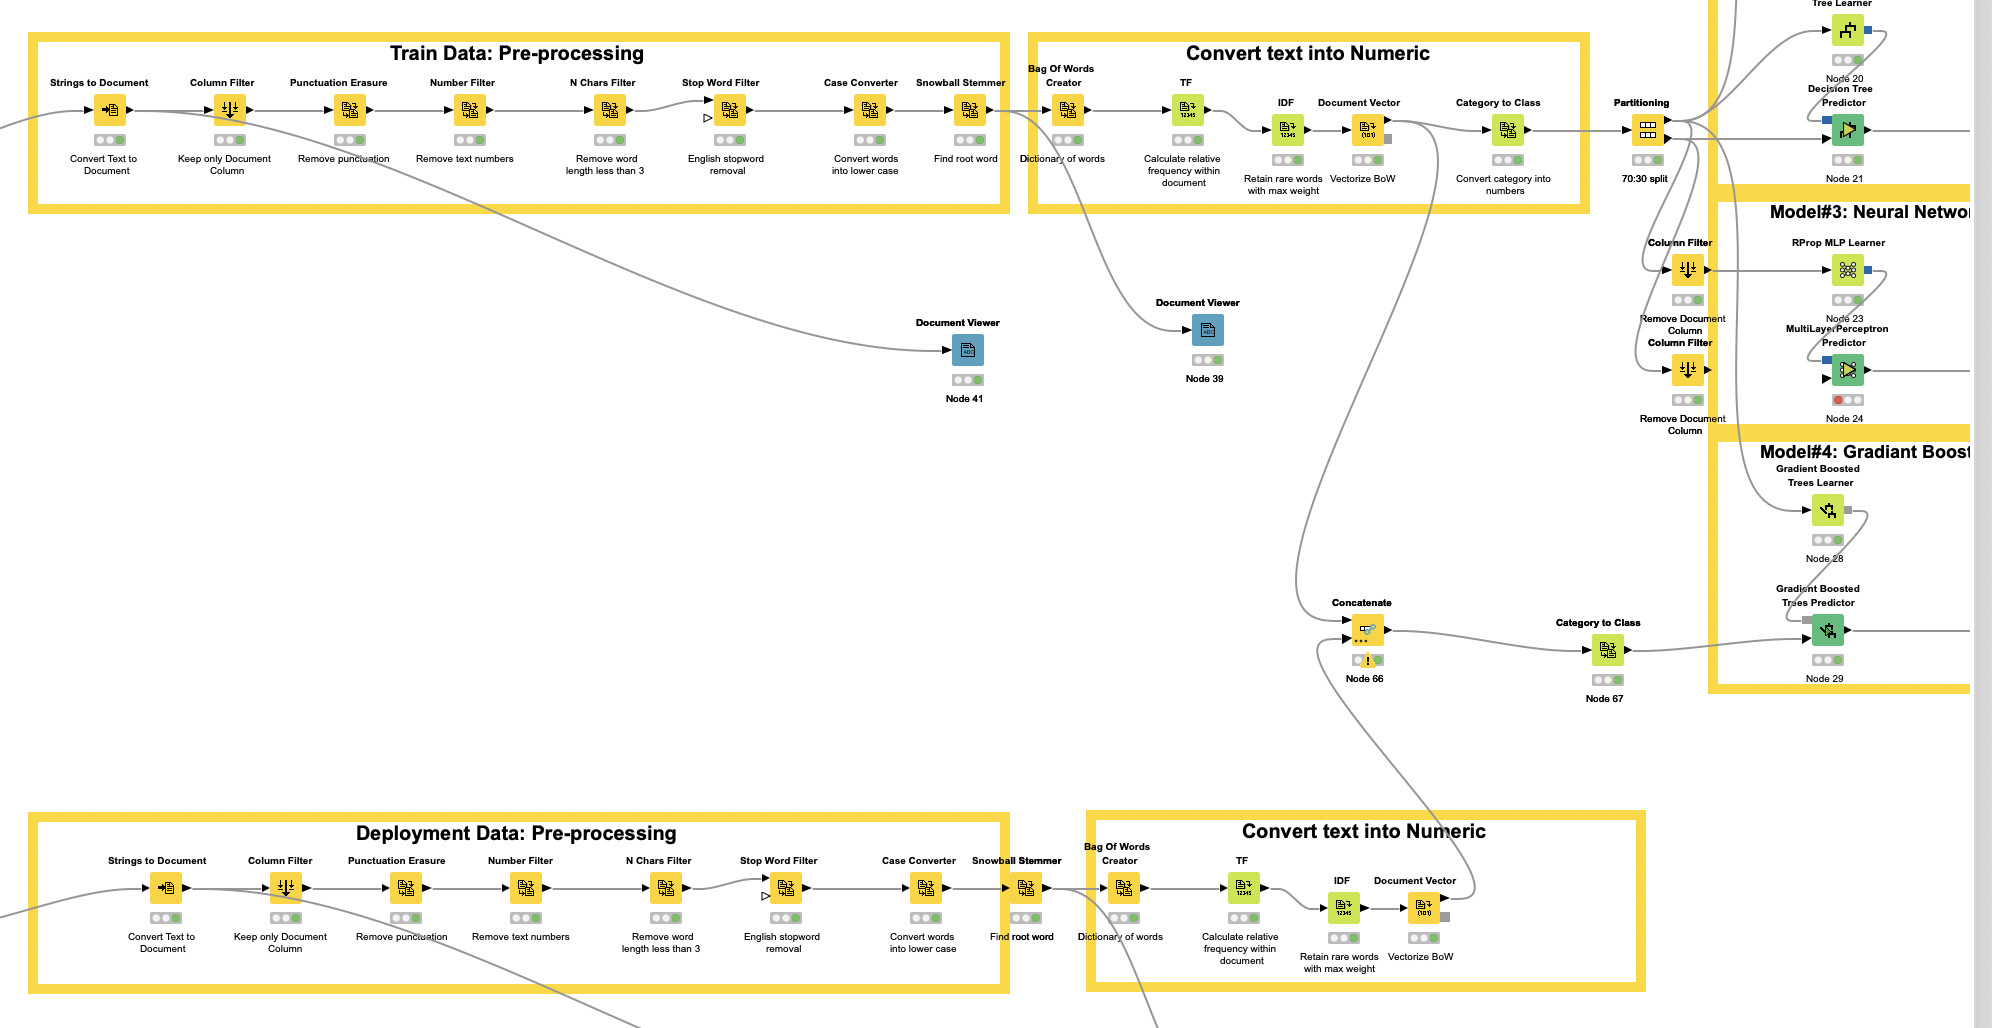
Description:
Training + Test data contains 110 rows
Deployment data contains 30 rows
Initially I encountered without ‘concatenate’. Error is “ column is missing”
To mitigate the issue, I used ‘Concatenate’ with Union as the option. Model prediction was successful wi th 94% accuracy.
Questions)
Is this the expected way to solve such text classification problem with new fresh deployment data?
Am I missing anything here?