How to use Workflow Executor for Apache Spark
Hi guys,
I would use the KNIME Workflow Executor for Apache Spark. Is there a example workflow or a description for this usage?
I’ve installed the KNIME Workflow Executor for Apache Spark (Preview). For our hadoop cluster I used the Create Spark Context (Livy) Node, Spark Version 2.3, and HDFS Connection Node, HDFS 3.1.1.
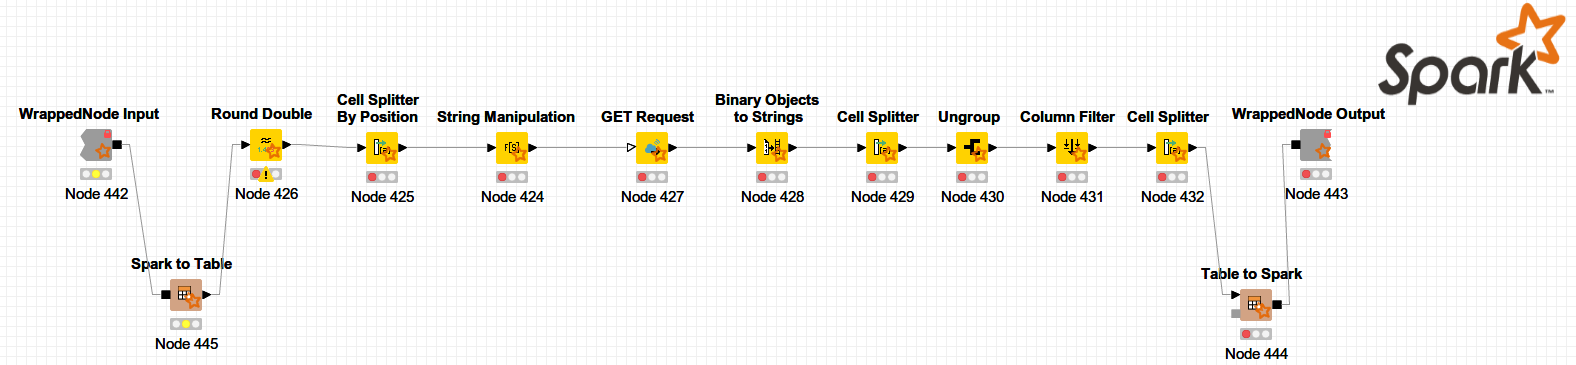
I’ve build a small workflow with Non-Spark-Nodes inside a wrapped Metanode.
Spark Data Ports (in and out).
Inside the Metanode a Spark to Table Node and a Table to Spark Node and some Non_Spark-Nodes.
I’ve connected the Metanode with a Table to Spark Node outside the Metanode to ingest the table data.
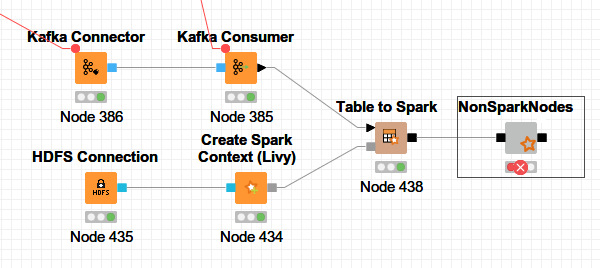
I’ve got the Error: KNIME Workflow Executor for Apache Spark requires spark.knime.knosp.knimeDir to be set in the Spark settings.
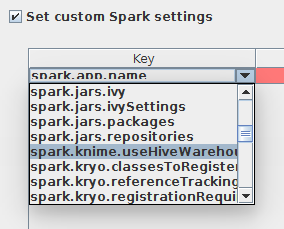
But there is no key spark.knime.knosp.knimeDir to set custom Spark settings (Create Spark Context (Livy)).
Any suggestions?
Regards
Andrew