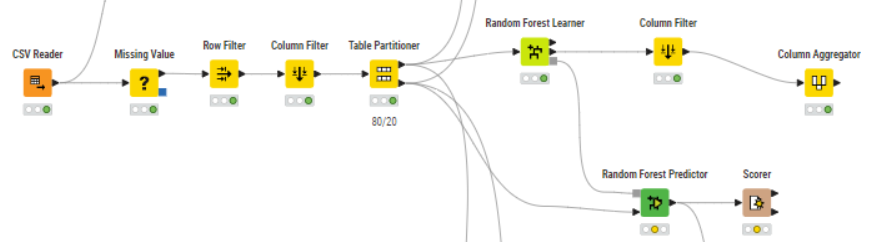
Determining the most important variables for Random Forest
Hi! I’m working on an assignment that tells me to interpret the variables and name the most important variables when using a trained random forest model. I’ve been trying to search for a good way to do this but so far I’m not finding any good explanations. In fact, I seem to be reading some mixed things about how to do this in Knime. Asking my professor didn’t actually help either as he told me to just search Knime Hub, or to just manually look through the tree view for the first tree in the model (which doesn’t make sense to me with a random forest?). I feel like I should use the attribute statistics but the professor disagreed when he saw the candidate columns? Am I supposed to just sum up the values for each split level per variable? Does anyone know of any good sources that helps me figure this out?
I’m just following a basic workflow like this: