Big Data join
Hi,
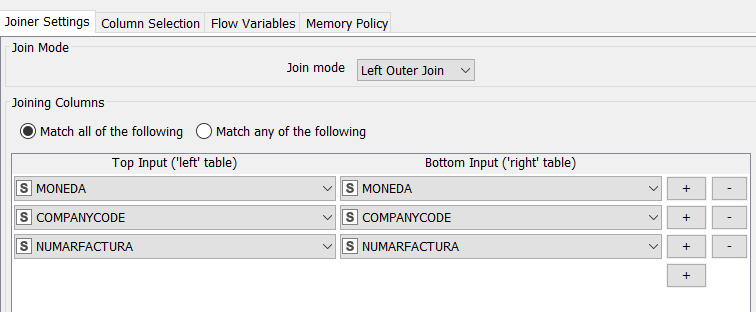
I have to create a workflow with two input files, each of around 20 mil rows. I have to compare the data from each of the tables, based on 3 columns see below.
The problem is that with my 4GB RAM allocation this does not work and crashes after around 40 minutes.
I tried using row sampling and it seems that I can manage to do 2 mil rows at a time fairly quickly using Big Data Environment and Spark.
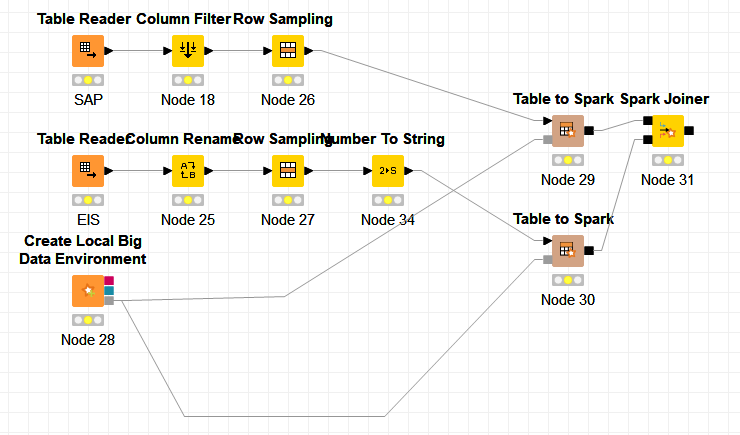
However, I do not know how to make this into a loop so that the workflows executes each 2 mil rows iteration, joins the data and then outputs it to a concatenate node or something else so that the “final” output is the sum of all iterations. As you can see in the joiner picture, I am interested in adding in table A, all rows that match the criteria.
I have tried using a chunk loop start node, however I don’t know how to join this (it gives the error “Unable to merge flow object stacks: Conflicting FlowObjects: <Loop Context”).
All the help or suggestions are very much appreciated.
Regards,